diff --git a/.github/RELEASING.md b/.github/RELEASING.md
index 0baaa41..ca0d8c6 100644
--- a/.github/RELEASING.md
+++ b/.github/RELEASING.md
@@ -26,6 +26,14 @@ Documentation edits usually do release, on purpose: `make skills` copies the doc
installed skill stays in step with the docs. A homepage or styling change touches only `website/`
and does not.
+Merge pull requests one at a time, each with its branch up to date with `main`. The release
+workflow only trusts a release base whose tree passed Verify on the pull request that produced
+it. If two pull requests merge back to back, `main` holds a combination no pull request verified,
+and the release workflow stops before it refreshes the release pull request's lockfiles. A later
+run that leaves the release pull request unchanged does not repair it. To recover, close the
+release pull request, then merge the next up-to-date pull request; Release Please opens a fresh
+release pull request from the verified tree.
+
## One-time setup
A repository administrator does these once, in a browser:
diff --git a/.github/demos/check-fix.gif b/.github/demos/check-fix.gif
index 7cdbd1e..e0a8abd 100644
Binary files a/.github/demos/check-fix.gif and b/.github/demos/check-fix.gif differ
diff --git a/.github/sqlclean-logo-dark.png b/.github/sqlclean-logo-dark.png
new file mode 100644
index 0000000..4ad21ee
Binary files /dev/null and b/.github/sqlclean-logo-dark.png differ
diff --git a/.github/sqlclean-logo-light.png b/.github/sqlclean-logo-light.png
new file mode 100644
index 0000000..7bc3fc3
Binary files /dev/null and b/.github/sqlclean-logo-light.png differ
diff --git a/README.md b/README.md
index c1d5eb0..845e779 100644
--- a/README.md
+++ b/README.md
@@ -1,41 +1,44 @@
-
+
+
+
+
+
The fastest SQL linter.
50× faster than sqruff. Lint 10,000 SQL files in under a second.Benchmarks
-
-
-
- Catch SQL mistakes, apply safe fixes, and format consistently. Add your own rules in Python.
-
+Catch SQL mistakes, apply safe fixes, and format consistently. Add your own rules in Python.
+SQLClean parses and checks SQL in Rust, and runs your Python Rules on statements it has already
+parsed.
+
```bash
uv tool install sqlclean # or: pip install sqlclean
```
-
+
-`sqlclean check` reports a bare `JOIN`, a `COUNT(1)` and a temporary table from a custom Rule.
-`sqlclean fix` applies the two fixes and formats the file; the custom Rule's finding has no fix,
-so it stays.
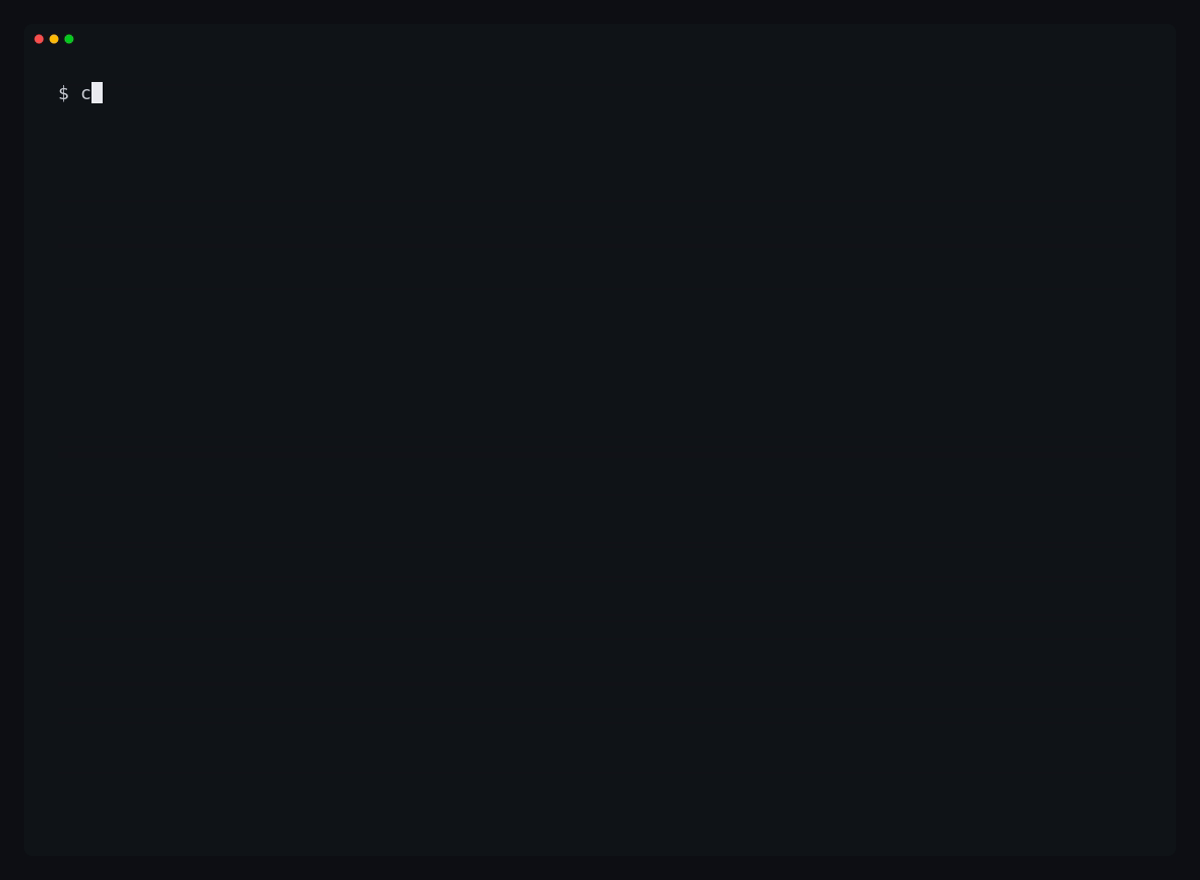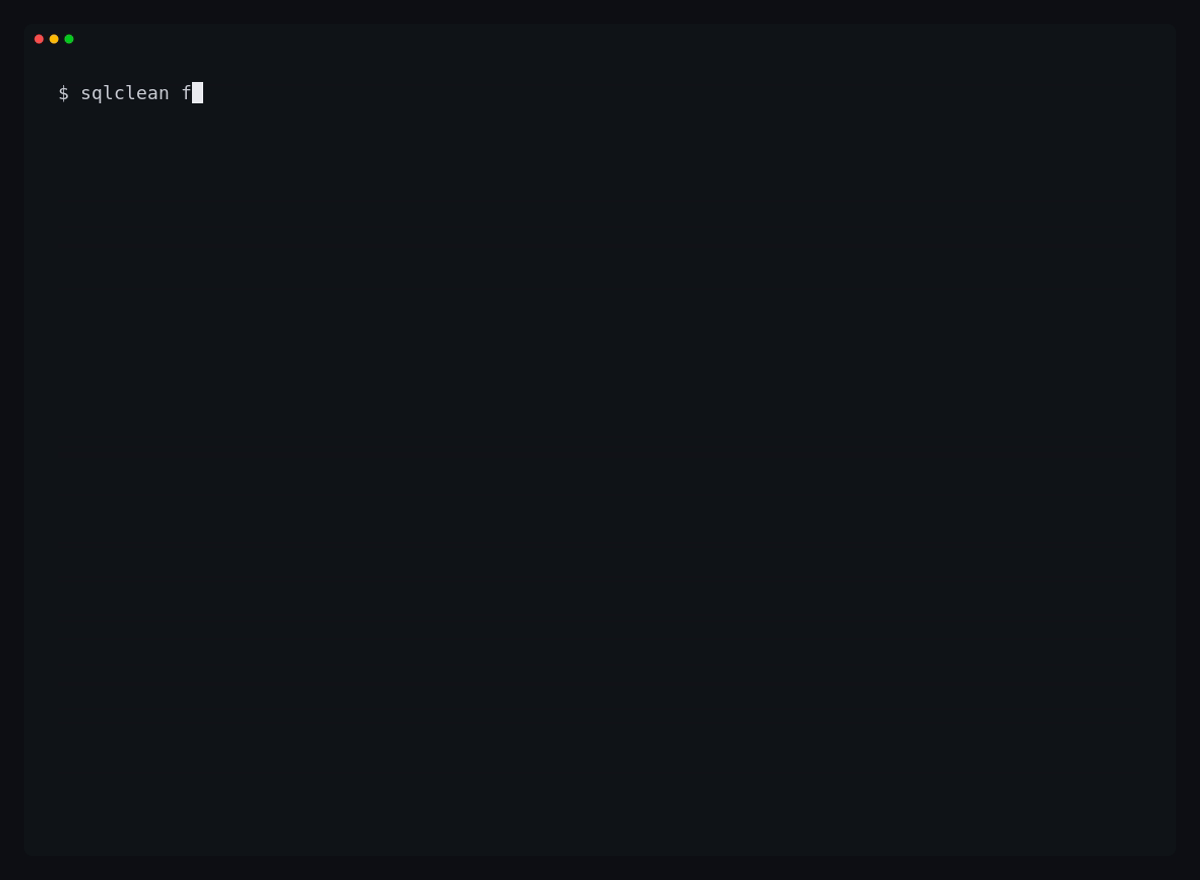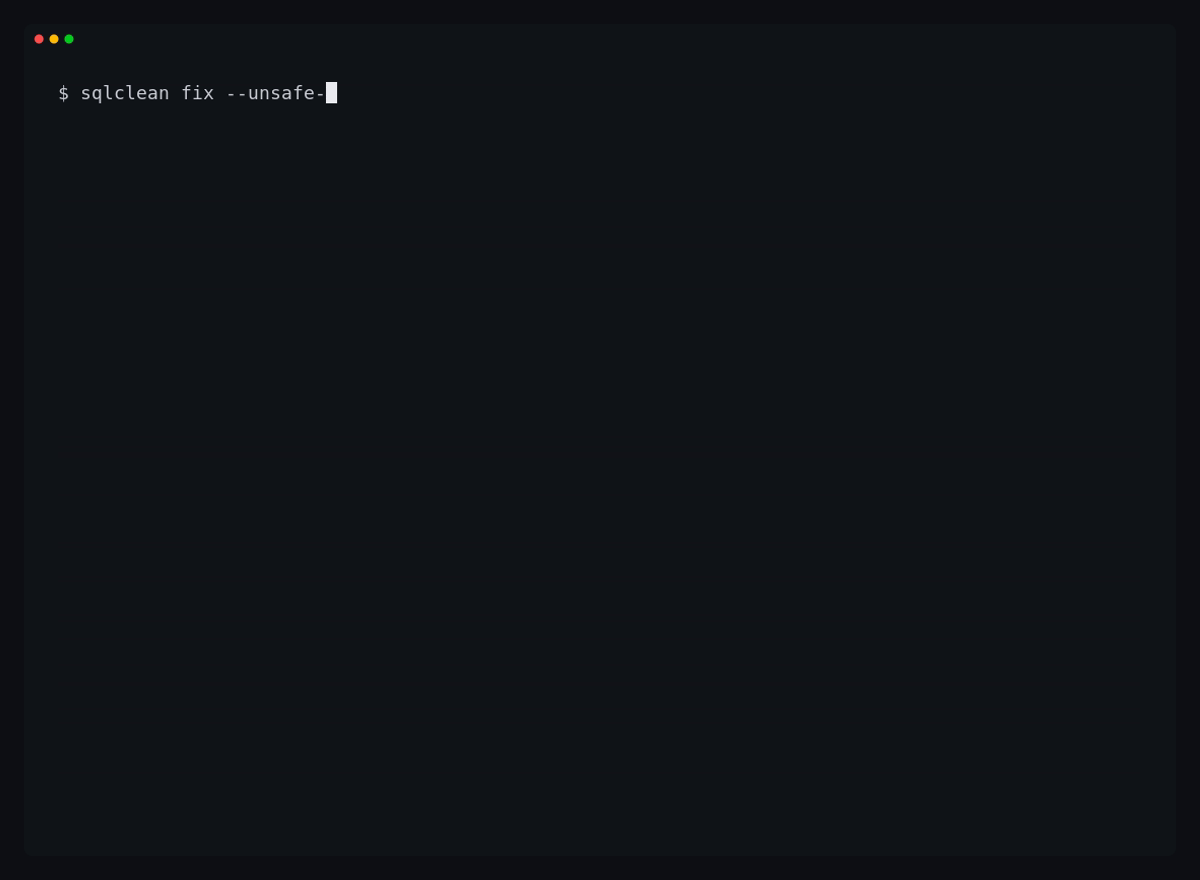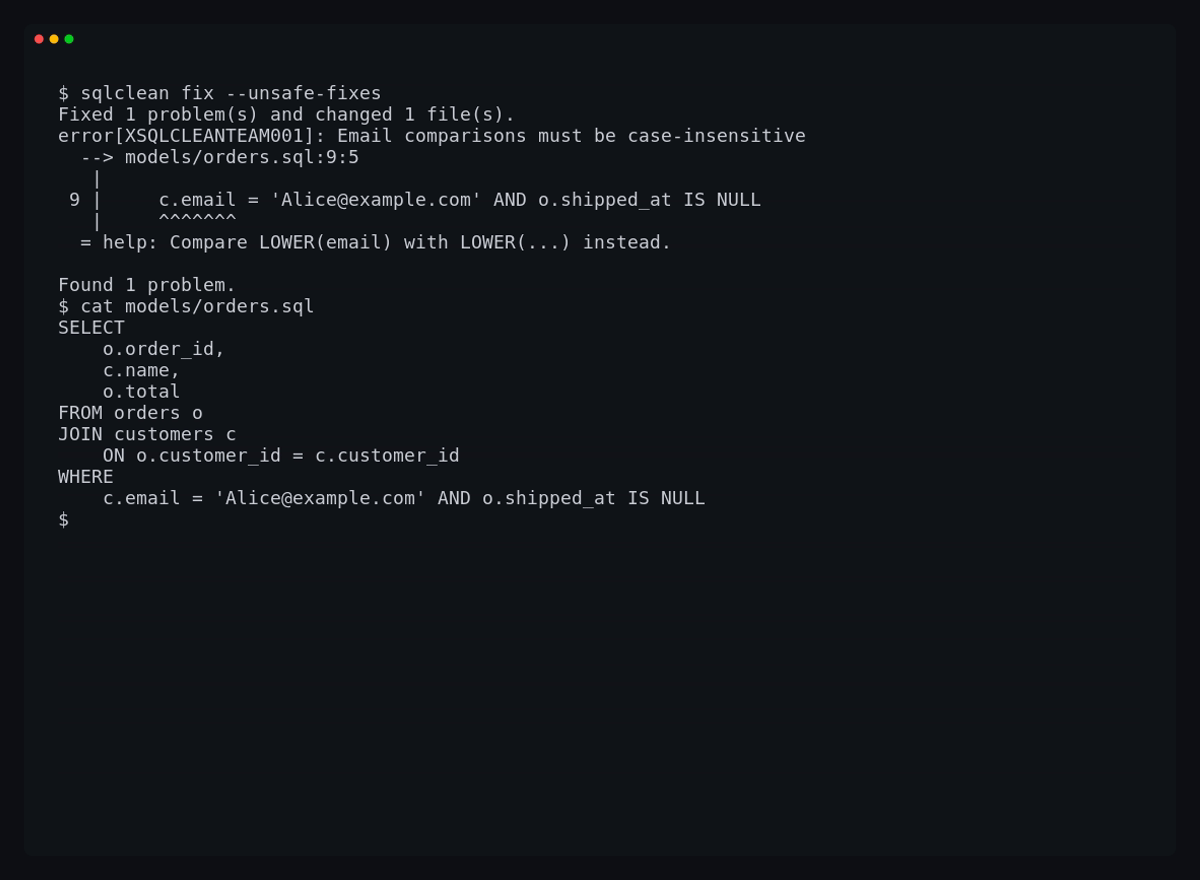
+`sqlclean check` reports an unused CTE, a temporary table from a custom Rule and a `= NULL`
+comparison that is never true. `sqlclean fix` applies the safe fix, removing the CTE, and formats
+the file. It leaves `= NULL` alone because rewriting it to `IS NULL` changes which rows match;
+`sqlclean fix --unsafe-fixes` applies that fix. The custom Rule's finding has no fix, so it stays.
## Speed
Linting the same 10,282 Snowflake SQL files on 4 CPUs, with no cache:
-| Command | Wall time | vs `sqlclean check` |
+| Command | Wall time | Time relative to `sqlclean check` |
|---|---:|---:|
| `sqlclean check` (default Rules) | **0.81 s** | 1× |
| `sqlclean check --select SQC` (all Rules) | **1.33 s** | 1.6× |
@@ -49,6 +52,18 @@ The tools don't check the same things, so see the
[benchmarks](https://sqlclean.io/docs/benchmarks/) for coverage, the corpus, the method and how
to run it yourself.
+## Quick start
+
+```bash
+sqlclean check # report findings in every .sql file under the directory
+sqlclean fix # apply safe fixes, then format
+sqlclean format # rewrite files in the canonical layout
+```
+
+Add a `sqlclean.toml` to choose a dialect, files or Rules. See the
+[quickstart](https://sqlclean.io/docs/quickstart/) and
+[configuration](https://sqlclean.io/docs/configuration/).
+
## Correct and safe
- **Rules for SQL that runs but is wrong.** Built-in Rules flag comparisons with `NULL`, `NOT IN`
@@ -88,18 +103,6 @@ Point `[rules] custom = ["sql_rules"]` in `sqlclean.toml` at it. See
[custom Rules](https://sqlclean.io/docs/custom-rules/overview/) and
[testing custom Rules](https://sqlclean.io/docs/custom-rules/testing/).
-## Quick start
-
-```bash
-sqlclean check # report findings in every .sql file under the directory
-sqlclean fix # apply safe fixes, then format
-sqlclean format # rewrite files in the canonical layout
-```
-
-Add a `sqlclean.toml` to choose a dialect, files or Rules. See the
-[quickstart](https://sqlclean.io/docs/quickstart/) and
-[configuration](https://sqlclean.io/docs/configuration/).
-
## Integrations
```yaml
diff --git a/website/recordings/README.md b/website/recordings/README.md
index 0076f23..d4af8a9 100644
--- a/website/recordings/README.md
+++ b/website/recordings/README.md
@@ -6,7 +6,7 @@ scripts are the source; the rendered GIF, MP4 and PNG files go to `out/`, which
| Demo | Shows |
|------|-------|
-| `check-fix` | `sqlclean check` reports built-in and custom findings, and `sqlclean fix` fixes and formats. |
+| `check-fix` | `sqlclean check` reports built-in and custom findings, `sqlclean fix` applies the safe fix and formats, and `sqlclean fix --unsafe-fixes` applies the unsafe one. |
The README uses `check-fix`, copied into `.github/demos/`.
diff --git a/website/recordings/prepare.sh b/website/recordings/prepare.sh
index 25eb94b..00621e6 100755
--- a/website/recordings/prepare.sh
+++ b/website/recordings/prepare.sh
@@ -9,22 +9,25 @@ mkdir -p "$dir"
cd "$dir"
case "$demo" in
check-fix)
- # One messy query: a bare JOIN, COUNT(1) and a temporary table that a custom Rule forbids.
+ # One query with a NULL comparison, an unused CTE and a temporary table that a custom Rule forbids.
mkdir -p models sql_rules
cat > sqlclean.toml <<'TOML'
dialect = "duckdb"
[rules]
-select = ["SQC025", "XSQC"]
custom = ["sql_rules"]
TOML
cat > models/orders.sql <<'SQL'
-select o.order_id, c.name, count(1) as items
-from orders o join tmp_customers c on o.customer_id = c.customer_id
-group by o.order_id, c.name
+with refunds as (
+ select order_id from payments where status = 'refunded'
+)
+select o.order_id, c.name, o.total
+from orders o
+join tmp_customers c on o.customer_id = c.customer_id
+where o.shipped_at = null
SQL
- cat > sql_rules/style.py <<'PY'
-from sqlclean import FixSafety, RuleContext, Statement, rule
+ cat > sql_rules/naming.py <<'PY'
+from sqlclean import Finding, RuleContext, Statement, rule
@rule(
@@ -33,28 +36,12 @@ from sqlclean import FixSafety, RuleContext, Statement, rule
remediation="Read from the published table instead.",
enabled_by_default=True,
)
-def temporary_table(*, statement: Statement, ctx: RuleContext) -> list:
+def temporary_table(*, statement: Statement, ctx: RuleContext) -> list[Finding]:
return [
ctx.finding(subject=statement, node=table)
for table in statement.tables
if table.name.startswith("tmp_")
]
-
-
-@rule(
- code="XSQCSTYLE001",
- message="COUNT(1) should be COUNT(*)",
- remediation="Write COUNT(*).",
- fixable=FixSafety.SAFE,
- enabled_by_default=True,
-)
-def count_one(*, statement: Statement, ctx: RuleContext) -> list:
- counts = {f.end + 1 for f in statement.functions if f.name.upper() == "COUNT"}
- return [
- ctx.finding(subject=statement, node=literal, fix=[ctx.replace(node=literal, text="*")])
- for literal in statement.literals
- if literal.text == "1" and literal.start in counts
- ]
PY
;;
*)
diff --git a/website/recordings/tapes/check-fix.tape b/website/recordings/tapes/check-fix.tape
index 20610b8..2138265 100644
--- a/website/recordings/tapes/check-fix.tape
+++ b/website/recordings/tapes/check-fix.tape
@@ -1,5 +1,5 @@
Source tapes/common.tape
-Set Height 820
+Set Height 880
Output out/check-fix.gif
Output out/check-fix.mp4
Hide
@@ -14,8 +14,26 @@ Type "sqlclean check"
Sleep 300ms
Enter
Wait@60s /\$\s*$/
-Sleep 3s
-Type "clear && sqlclean fix"
+Sleep 5s
+Hide
+Type "clear"
+Enter
+Sleep 300ms
+Show
+Type "sqlclean fix"
+Sleep 300ms
+Enter
+Wait@60s /\$\s*$/
+Sleep 1500ms
+Type "cat models/orders.sql"
+Enter
+Sleep 5s
+Hide
+Type "clear"
+Enter
+Sleep 300ms
+Show
+Type "sqlclean fix --unsafe-fixes"
Sleep 300ms
Enter
Wait@60s /\$\s*$/
@@ -24,4 +42,4 @@ Type "cat models/orders.sql"
Enter
Sleep 1s
Screenshot out/check-fix.png
-Sleep 8s
+Sleep 5s
 +
 +
 +