


FastMemory is an ontological clustering engine that transforms flat, unstructured text into a structured, agent-navigable functional memory graph using the Topology (Component, Block, Function, Data, Access, Event) taxonomy — no embeddings required.
Developed by FastBuilder.AI, FastMemory bridges the gap between shallow vector retrieval (RAG) and deterministic computational memory.
-
Benchmarks: FastMemory's results are being re-run with a public, reproducible harness, with fixed samples, CIs and losses reported as losses. Results appear here as they are verified. Earlier summary claims were withdrawn until they can be reproduced the same way.
-
Passage search (new in 0.4.10), SQuAD v1.1 validation (seed 0), recall@5 against a standard BM25: FastMemory's search is lexical only: words, stems and typo-tolerant word matching, with no embeddings. It wins when queries are misspelled, ties or loses slightly on clean questions (a loss at 2,000 paragraphs), and loses on short keyword queries. BM25 here is
rank_bm25's Okapi over the same passages.Query style 300 paragraphs, 600 questions: FastMemory / BM25 2,000 paragraphs and questions: FastMemory / BM25 Clean question 0.938 / 0.952 0.903 / 0.919 (loss) One misspelled word 0.893 / 0.893 0.825 / 0.829 Every long word misspelled 0.580 / 0.427 (win) 0.436 / 0.330 (win) Keywords only 0.808 / 0.843 (loss) 0.657 / 0.684 (loss) Misspelled keywords 0.658 / 0.052 (win) 0.499 / 0.015 (win) Win and loss: exact paired McNemar test, p < 0.05 (every labelled cell has p < 0.01). Unlabelled cells show no significant difference (p ≥ 0.07). Rates are exact counts rounded half up to three decimals, as in MahaBodi's BENCHMARKS.md. Median query time on an Apple M2 Pro: 0.05 ms (300 paragraphs) and 0.15 ms (2,000), or 0.5–1.7 ms for misspelled keywords. The harness and per-question results are public in the MahaBodi repository (
research/bench_retrieval_fastmemory.py). MahaBodi's lexical search, which this search was ported from, gets the same hit or miss on every question. -
Clustering benchmark: pre-registered in
benchmarks/PREREG_CLUSTERING.md(LFR and SNAP graphs, against Leiden, Infomap and Louvain), running now. Results will be published here, losses included. -
Production example (measured on the live deployment, 2026-09-29): a FastStudio deployment serving PubChem. The deployment is private, so these numbers can't be independently reproduced:
Measured Value Compounds 444,789 (PubChem CID 1–500,000, one of PubChem's 359 SDF files; 339 MB gzipped) Stored per compound about 258 characters of selected fields (name, formula, weight, H-bond counts, LogP, rotatable bonds, complexity) plus its topology Storage 0.79 GB of rows plus a 0.12 GB full-text index, in PostgreSQL Service process memory 78–89 MB resident; the data lives in the database, not in the process Embeddings none This is a selective, structured summary of each compound, not lossless compression of PubChem.
- Run the FastMemory Demonstration Notebook: Basic Topology Architecture.
- Run the FinanceBench Notebook: Advanced multi-hop financial reasoning.
Building reliable AI agents on top of massive codebases and datasets is incredibly hard. FastMemory directly solves the three biggest pain points developers face today:
- RAG Hallucinations: Standard vector similarity retrieves unrelated text chunks just because they share keywords (e.g., retrieving the "Login Code" when the user asked about the "Login Bug Ticket"). FastMemory provides Deterministic Pathfinding through isolated functional clusters.
- Context Fragmentation: Naive text chunking destroys logical boundaries, losing the surrounding context of a function. FastMemory parses semantic topologies into grouped Cognitive Blocks, providing the AI with sibling functions and deterministic access restrictions.
- Graph DB Sync Overhead: Piping hierarchical data into Neo4J normally requires complex, fragile NLP and ETL pipelines. The FastMemory Rust engine does this natively in milliseconds using structural Louvain clustering.
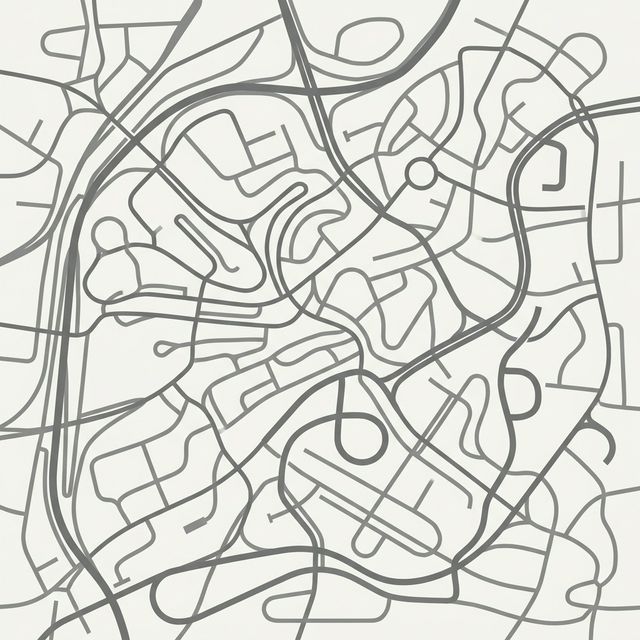
Imagine opening Google Maps, but all you can see are roads and paths. There are no building names, no entry gates, no transaction information for the buildings, and no communication routing.
If you asked a humanoid robot to navigate to a hospital using this map, it would only see a "road to a doctor", a "road to a bed", a "road to a nurse", and a "road to a pharmacy." It would have a profoundly hard time knowing the modes and modality of how to actually behave, act, and pursue every target differently depending on context.
That is exactly what happens when you use standard RAG, semantic ontologies, or flat vector graphs.
| Standard Ontology / RAG | FastMemory Topology Map |
|---|---|
 |
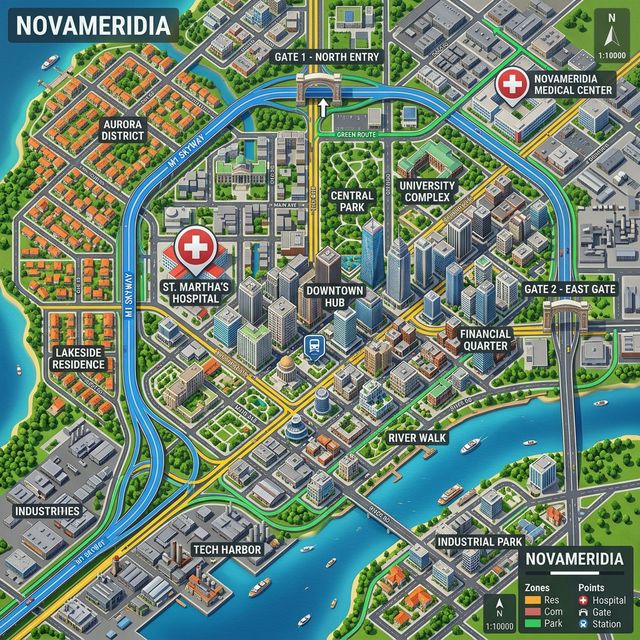 |
You simply have node-to-node semantic edges. You possess the "roads" (cosine similarity), but you lack the "buildings" (Functional Components) and the "rules of entry/engagement" (Access and Events).
FastMemory solves this. We utilize high-speed Community Detection (Louvain clustering) to mathematically derive and enhance this network of data for direct AI usage, translating raw text into executable cognitive blocks.
- Topology Ontology: Information isn't just stored; it is classified into Components, Blocks, Functions, Data, Access restrictions, and Events.
- Deterministic Pathfinding: Eliminates RAG hallucinations. An AI doesn't "guess" the answer based on semantic proximity; it traverses a rigorous, rule-based logic graph.
- The Agentic Query Engine: Deep recursive subtree targeting. When you query FastMemory, it doesn't just return a matching string—it returns the deepest logical encompassing Block, providing the AI with sibling functions and contextual boundaries.
- Production Ready: Designed to scale from local development to large-scale production deployments with graph databases like Neo4J.
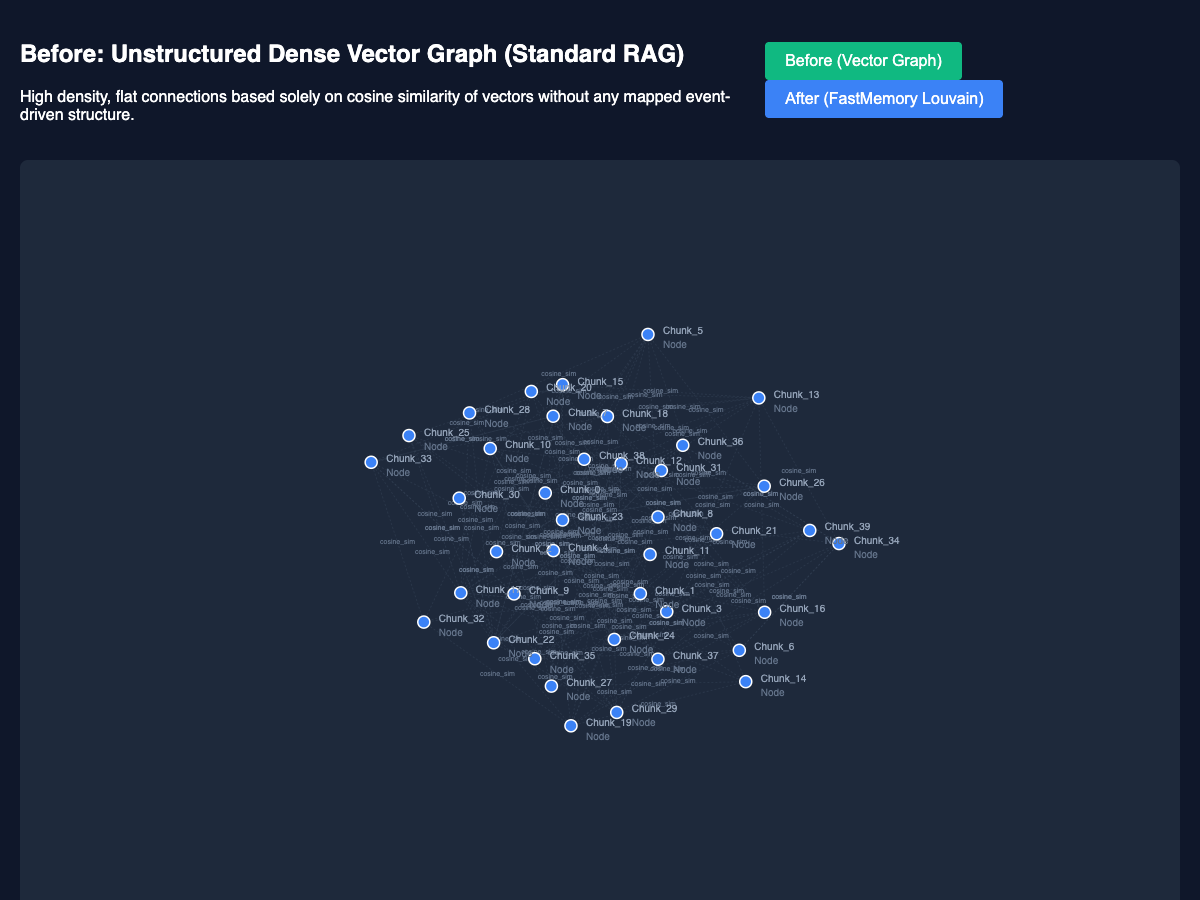
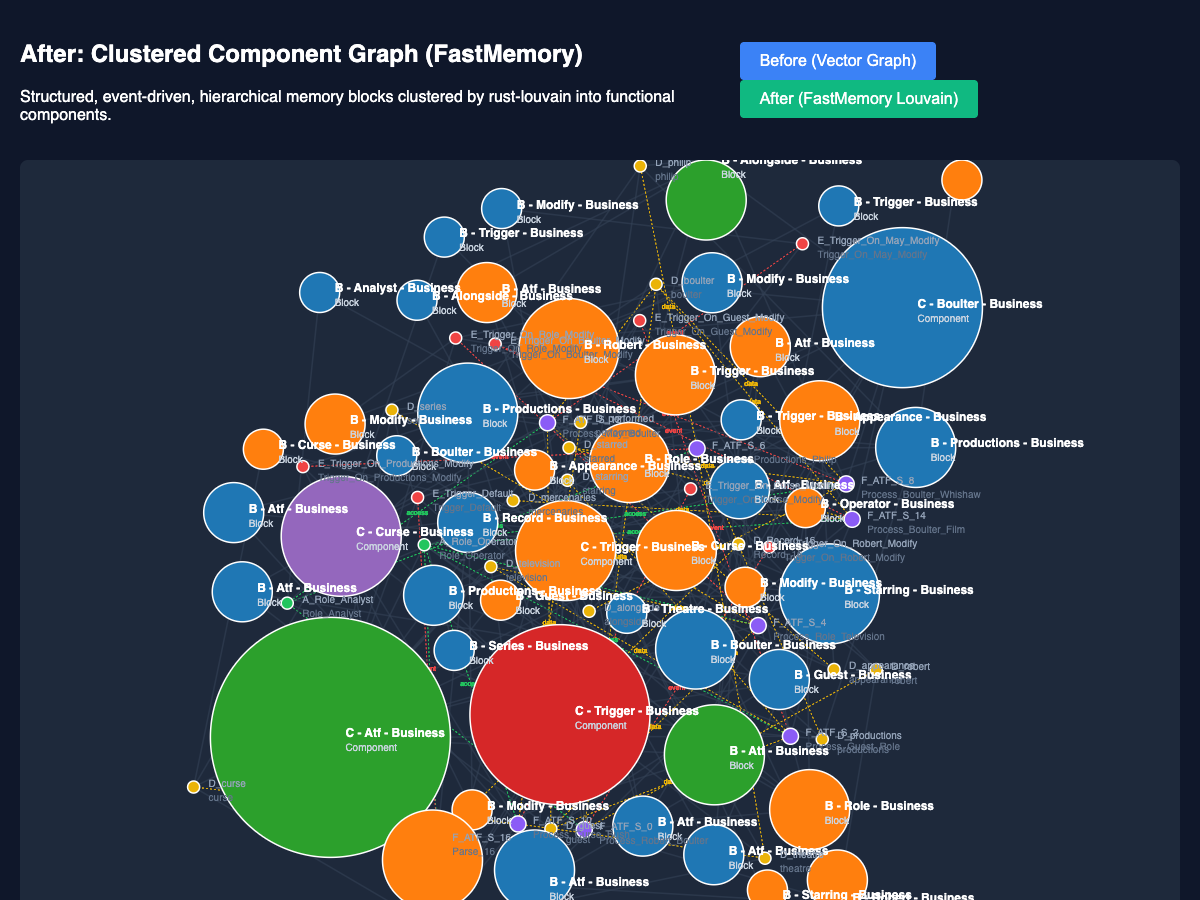
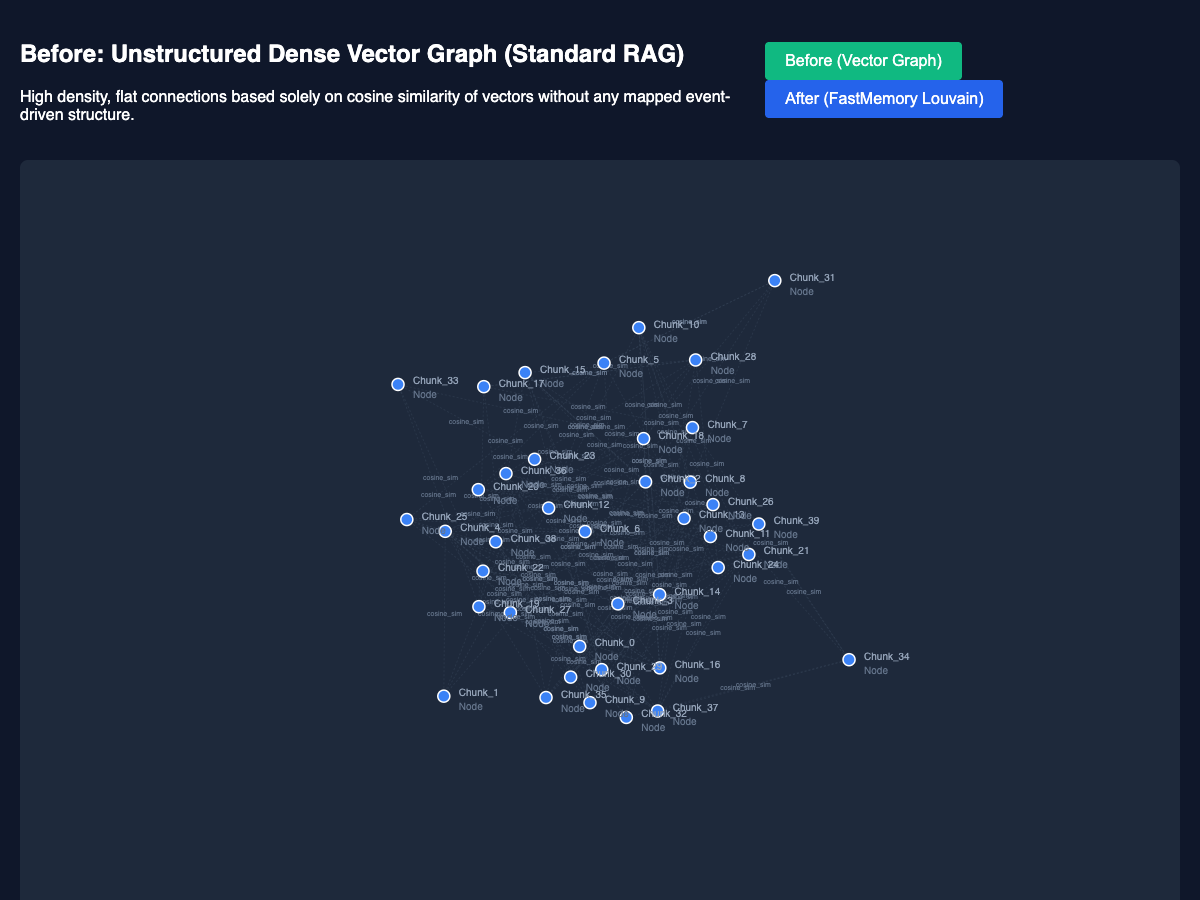
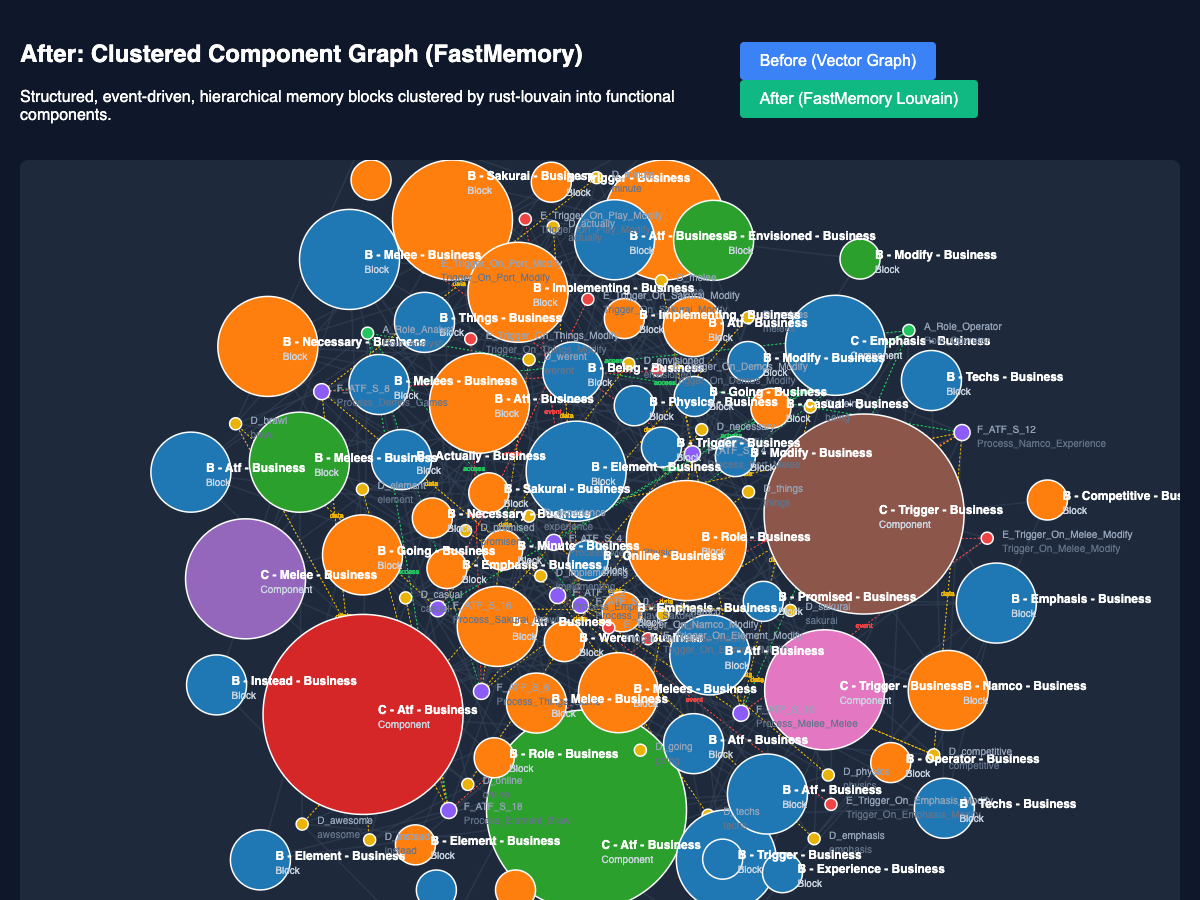
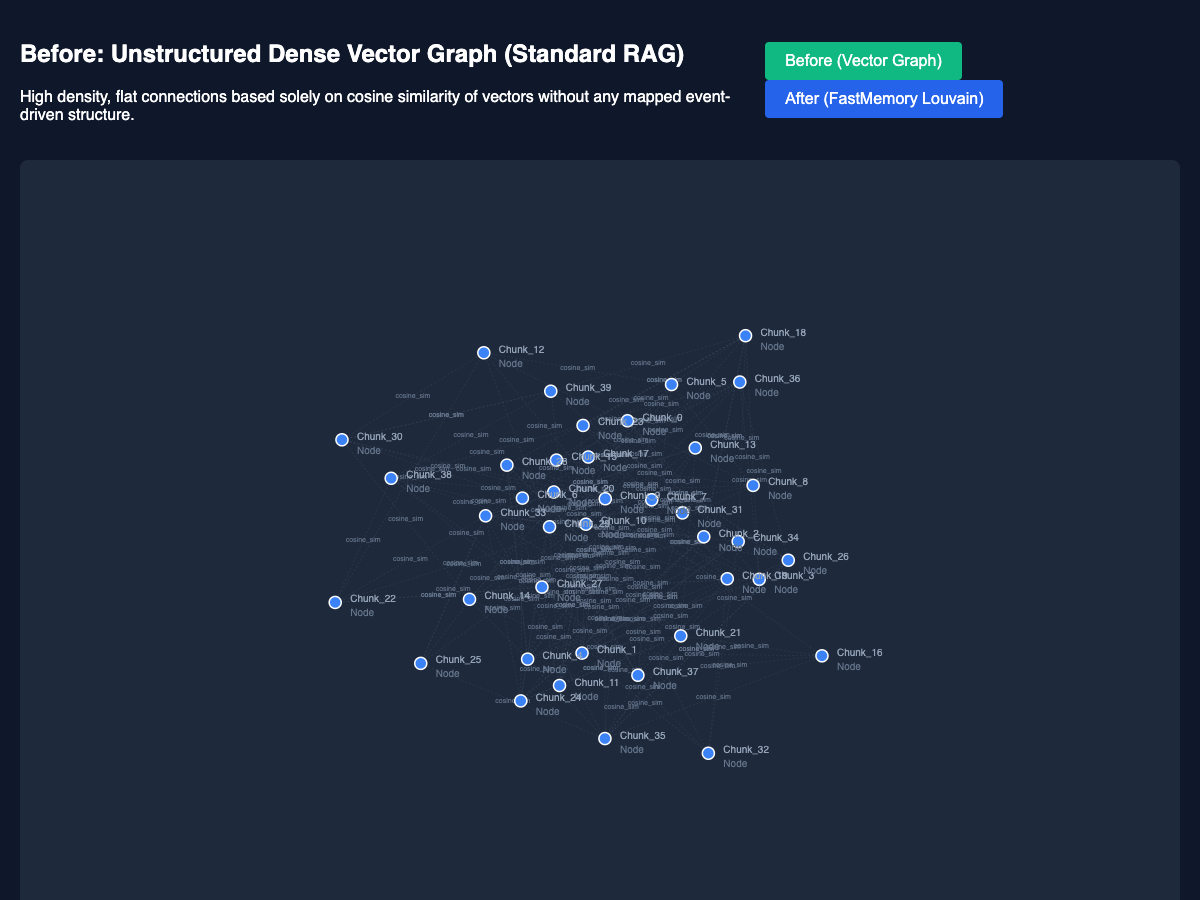
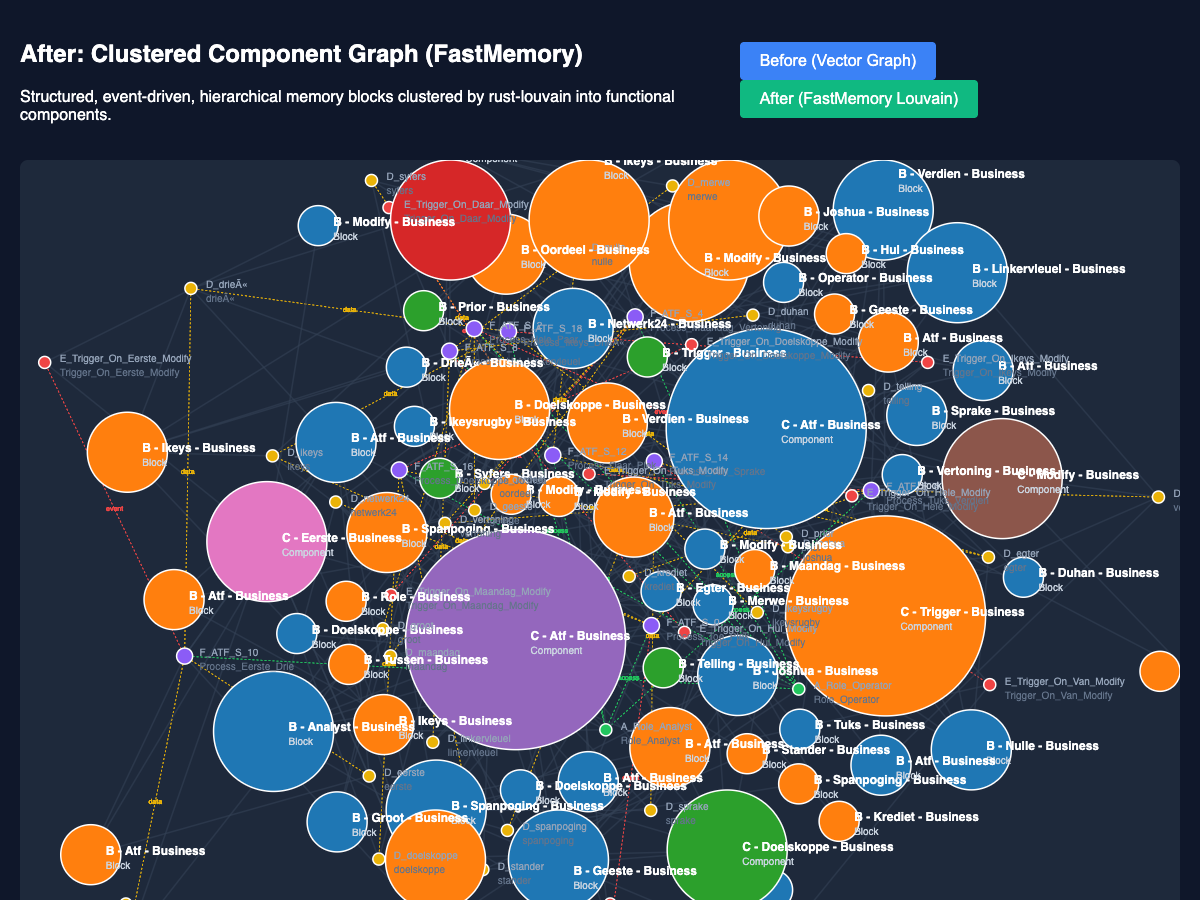
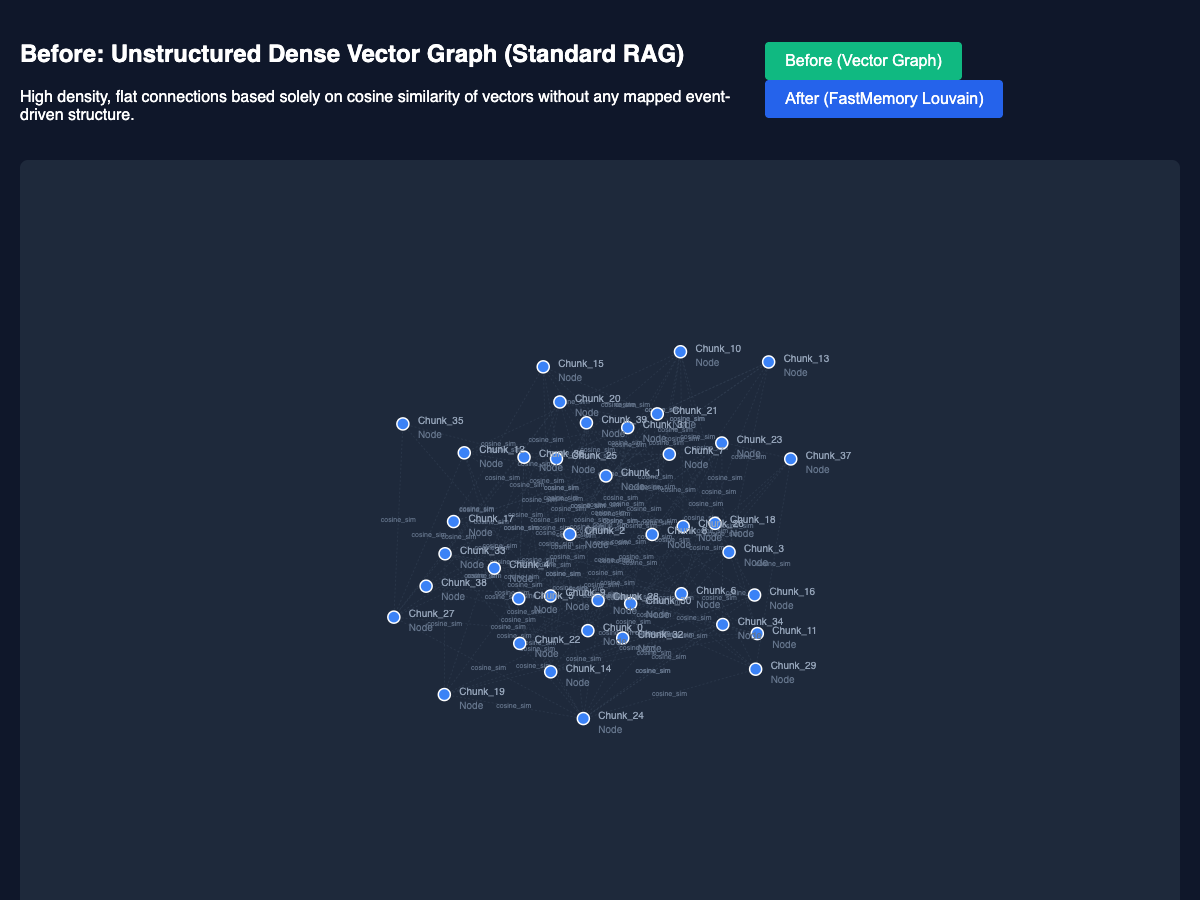
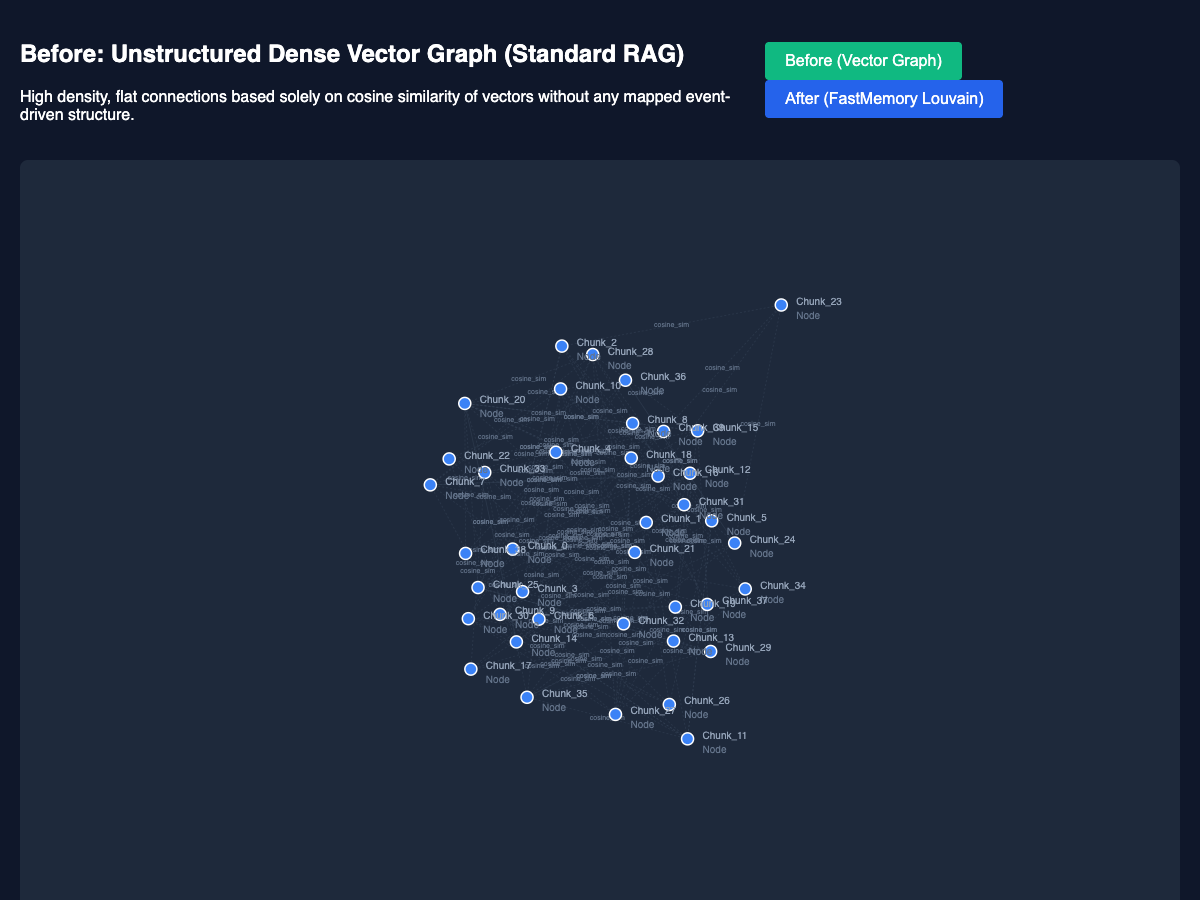
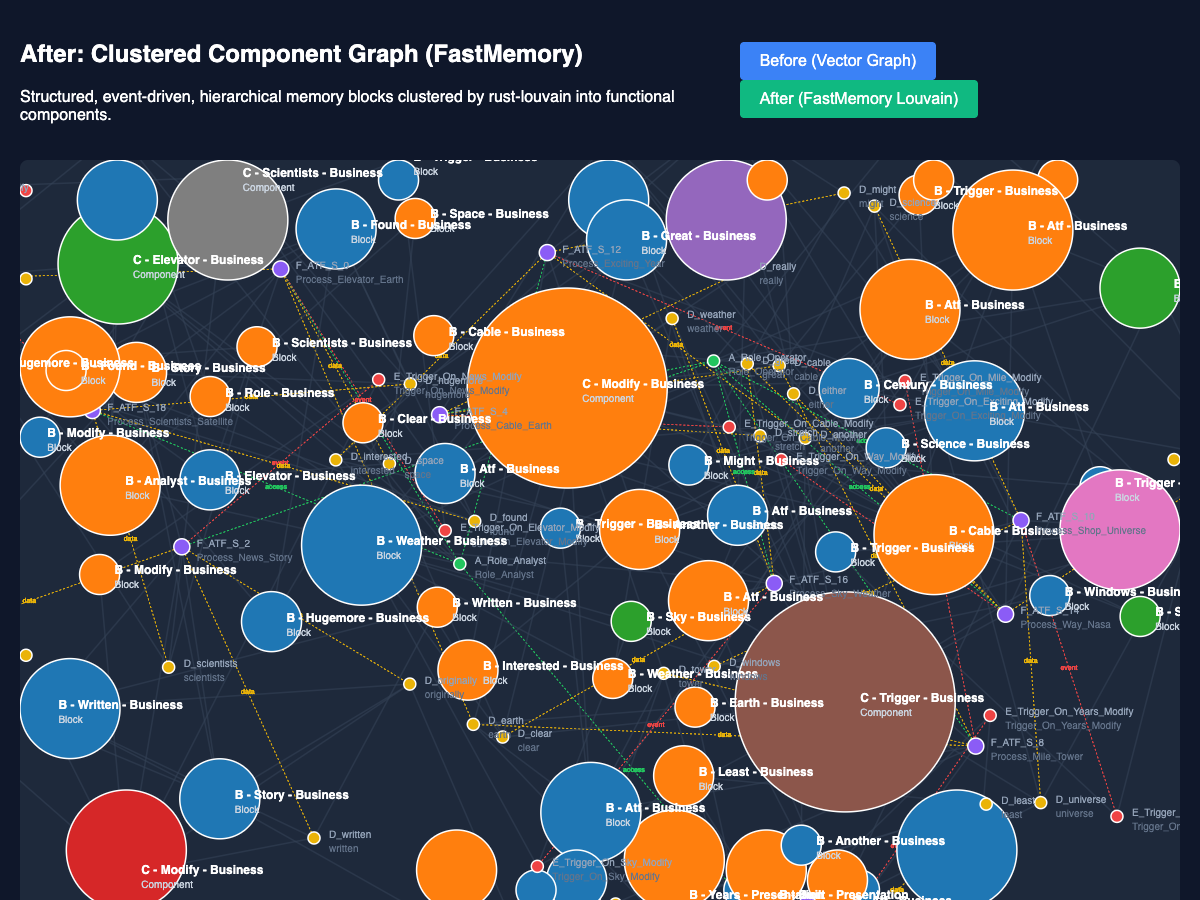
Standard vector RAG databases index chunks individually, often losing the multi-hop reasoning capability required to trace dependencies. FastMemory restructures these into event-driven, hierarchical memory blocks.
(You can open the interactive D3.js visualizations directly in your browser from the example/ directories!)
| Before: Flat Semantic Vectors | After: Clustered Functional Memory Graph |
|---|---|
 |
 |
| Before: Flat Semantic Vectors | After: Clustered Functional Memory Graph |
|---|---|
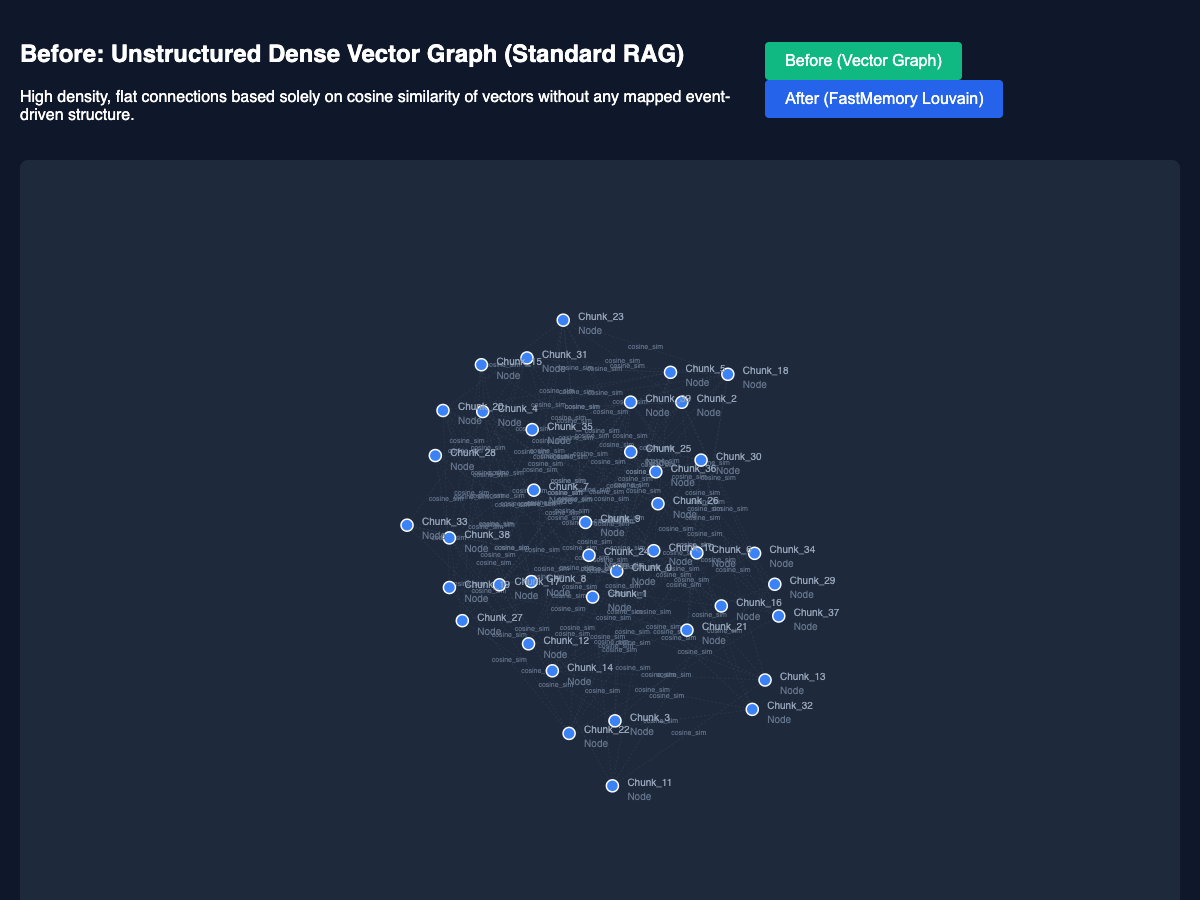 |
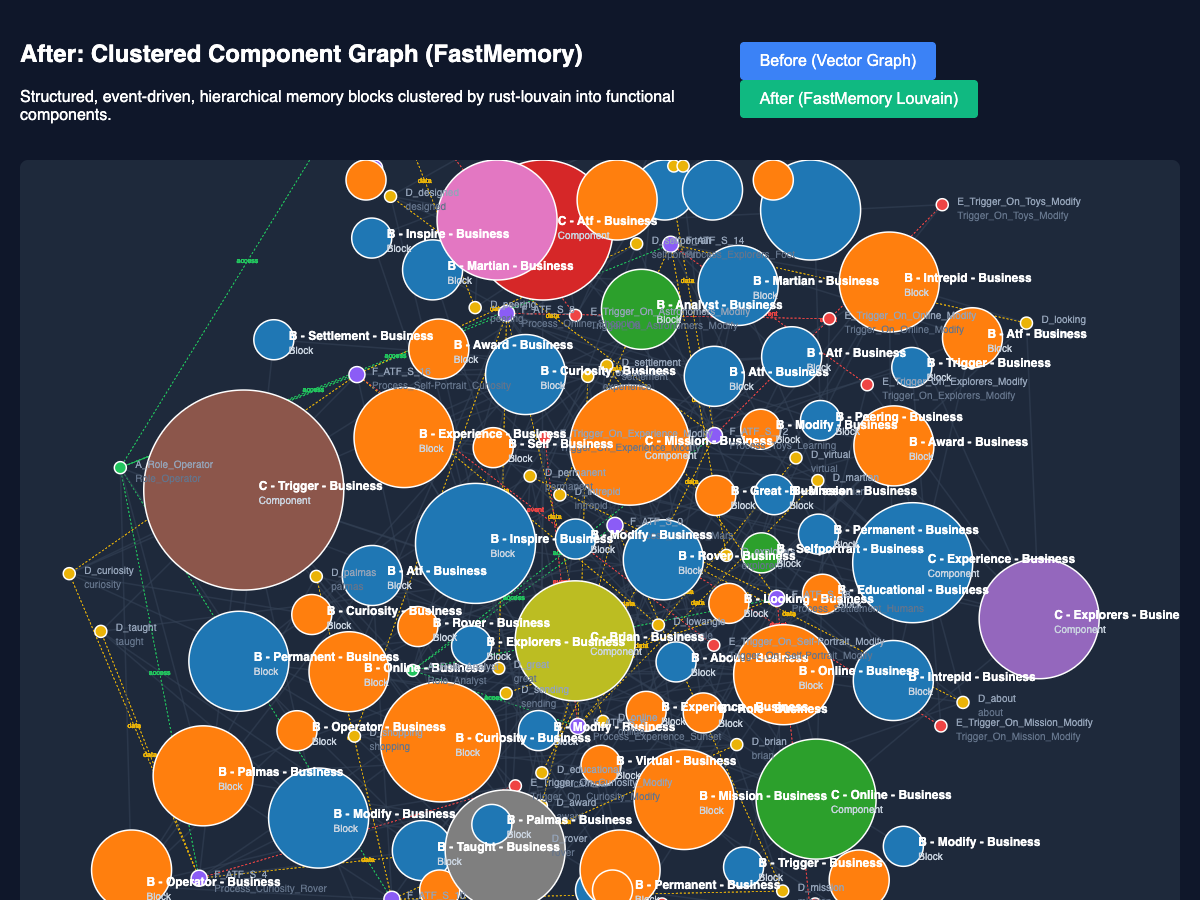 |
| Before: Flat Semantic Vectors | After: Clustered Functional Memory Graph |
|---|---|
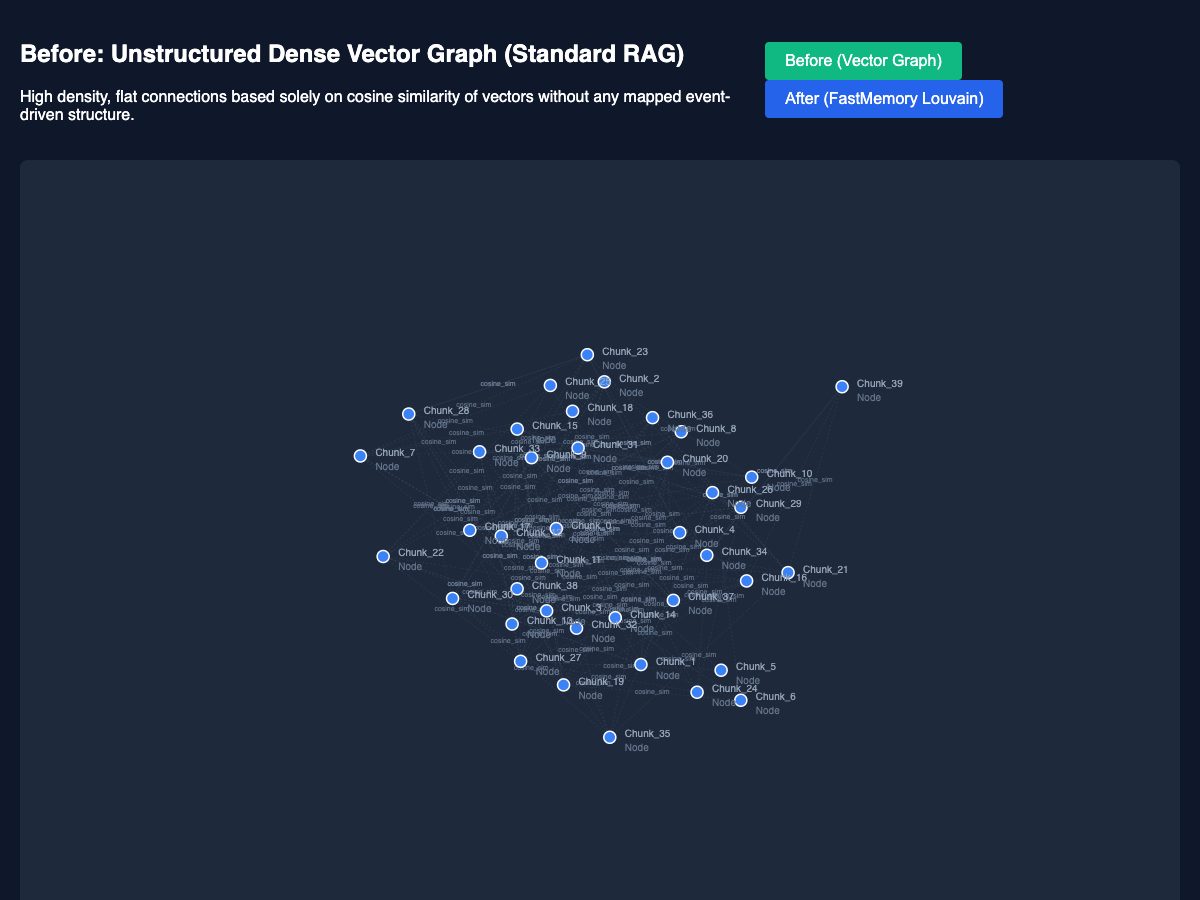 |
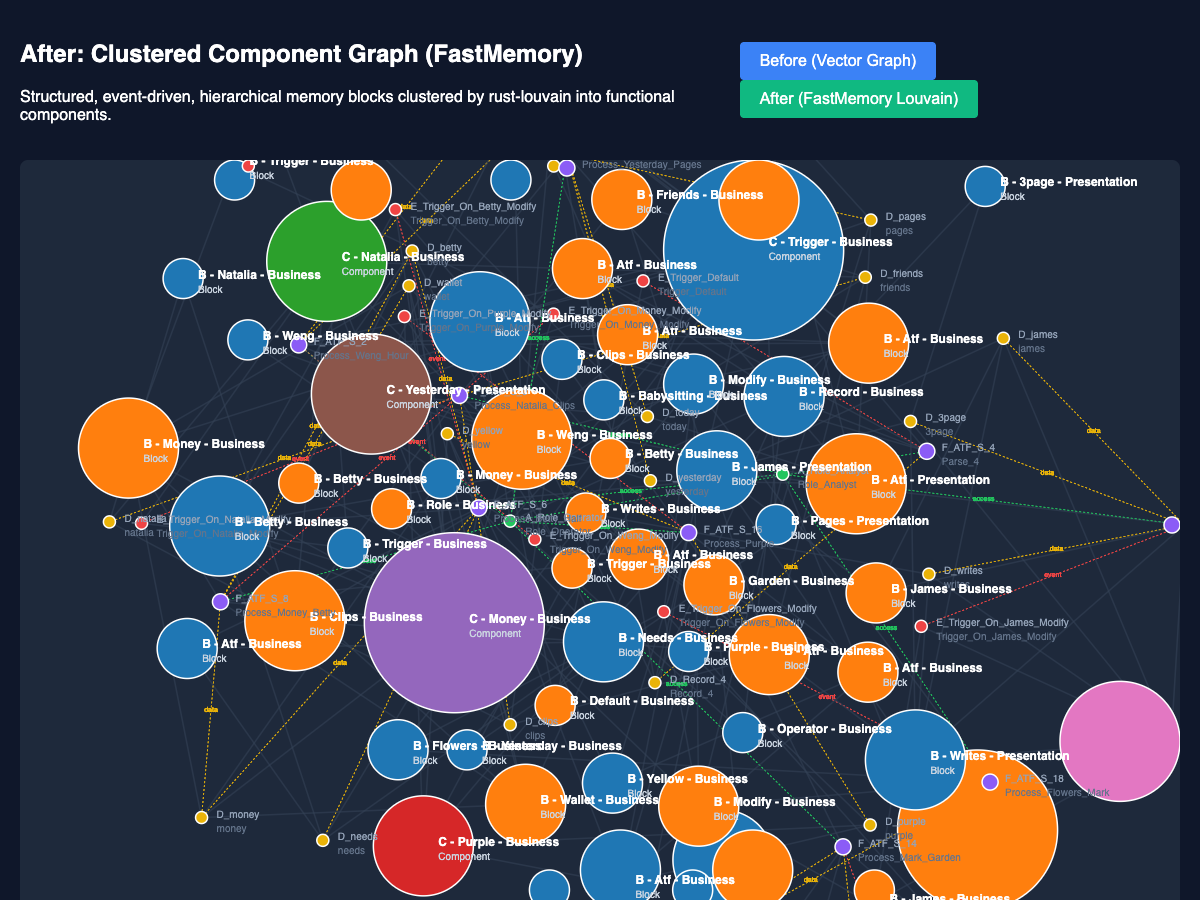 |
| Before: Flat Semantic Vectors | After: Clustered Functional Memory Graph |
|---|---|
 |
 |
| Before: Flat Semantic Vectors | After: Clustered Functional Memory Graph |
|---|---|
 |
 |
| Before: Flat Semantic Vectors | After: Clustered Functional Memory Graph |
|---|---|
 |
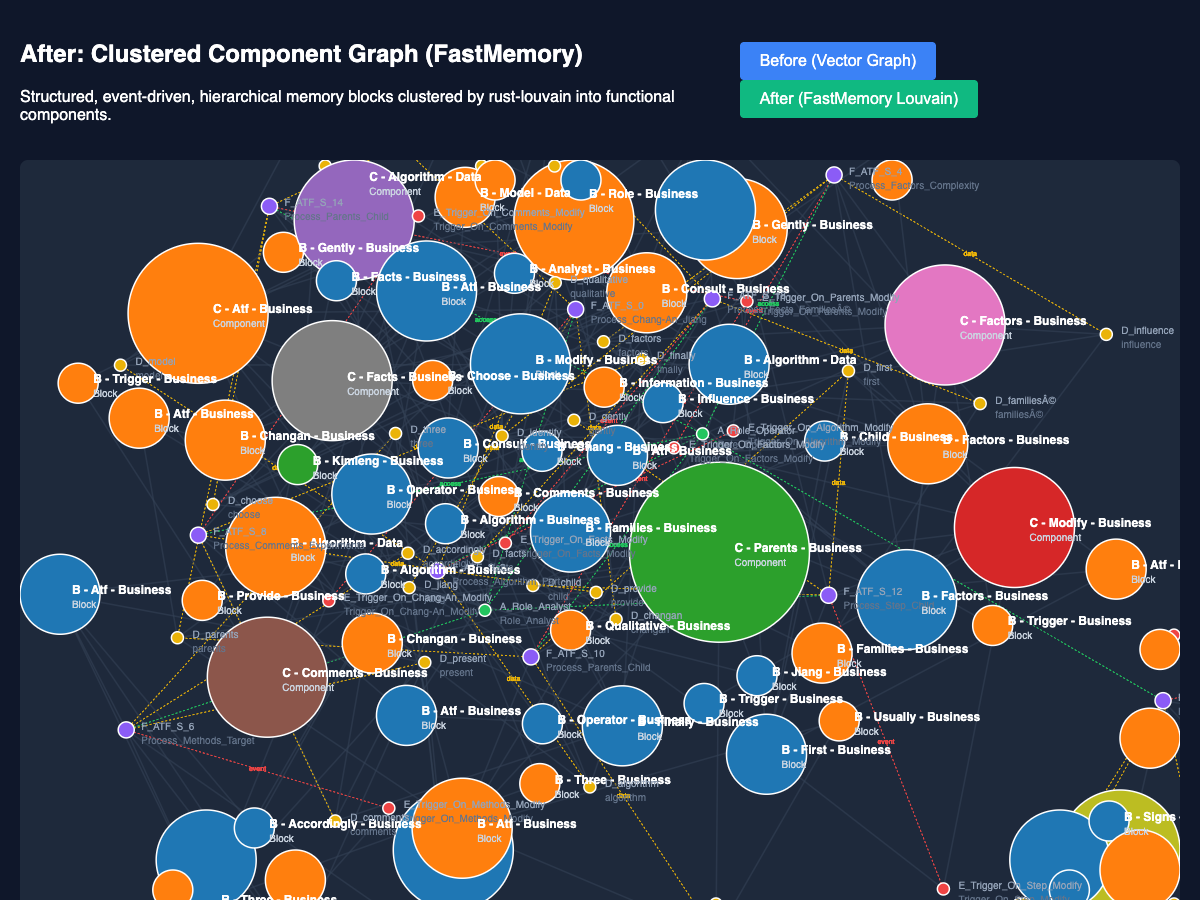 |
| Before: Flat Semantic Vectors | After: Clustered Functional Memory Graph |
|---|---|
 |
 |
Rust (Cargo) - CLI Utility
To install the standalone fastmemory CLI tool for terminal, server, or MCP usage:
cargo install fastmemoryPython (PyPI) - Native Import To install the high-speed Python module (built natively via PyO3) for direct integration into your Python AI applications:
pip install fastmemoryFastMemory can be utilized natively from the command line, spun up as a REST server, or imported directly into your Python scripts.
# Build the memory graph from an ATF Markdown file
$ fastmemory build data/input.md

# Instantly query the hierarchical graph
$ fastmemory query data/input.md "reimbursement"By utilizing our pip module, your Python loops can pass markdown directly to the compiled Rust engine without any JSON/CLI overhead. The resulting graph JSON is computed instantly via Louvain community detection.
import fastmemory

# 1. Define or fetch your raw Action-Topology Format (ATF) text
markdown_text = """
## [ID: auth_module]
**Action:** Validate_Token
**Data_Connections:** session_uuid
**Access:** Role_Admin
**Events:** User_Login
"""

# 2. Pass strings synchronously into the Rust engine
topology_json_graph = fastmemory.process_markdown(markdown_text)

print(topology_json_graph)FastMemory ships with a highly optimized embedded Axum web server and MCP (Model Context Protocol) integration for AI agents:
# Boot the REST API
$ fastmemory serve data/input.md --port 16743
# Query: curl http://localhost:16743/query?q=reimbursement

# Boot standard Stdio MCP (for Claude / Gemini IDE integration)
$ fastmemory mcp data/input.mdIn addition to positional file arguments, FastMemory supports flexible ingestion for dynamic pipelines:
- Local Directories (
--data): Pass a local directory to parse and cluster multiple ATF Markdown files continuously.$ fastmemory build --data /var/lib/fastmemory/data
- Remote Pipelines (
--datahost): Bind directly to Data Warehouses (Snowflake, BigQuery), Data Lakes (Databricks, Fabric), or S3 by passing a connection URI. FastMemory will securely intercept the URI and dynamically ingest the remote structures.$ fastmemory serve --port 16743 --datahost postgres://db_user:secret@localhost:5432/app $ fastmemory mcp --datahost s3://corporate-bucket/atfs/
Tip
Large Scale Graph DB Memory: When scaling FastMemory beyond local processing, the clustered JSON output explicitly maps into systems like Neo4J. FastMemory naturally supports partial topology updates. Please read our Production Scaling & Graph DB Ingestion Guide for detailed Python and Cypher deployment patterns.
Data access within FastMemory is rigorously secured at the graph layer. Utilizing the A_ (Access) node topology, you can map federated IAM rules (like AWS IAM or Azure AD) directly onto specific memory blocks.
- Wrapper Implementation: Place an API Gateway ahead of
fastmemory serveto enforce standard OAuth/SAML. - Code-Level Auth: AI agents parsing the memory graph will inherently see the
A_Role_Adminnodes attached to functions, allowing the agent to deterministically self-regulate access before taking action.
For a hands-on technical demonstration of how FastMemory replaces Vector RAG with deterministic Topology grounding, explore our interactive Jupyter Notebooks:
- Basic Global Topology Notebook: Learn the core LangChain grounding loop and ATF extraction.
- FinanceBench Notebook: Advanced demonstration of multi-hop financial reasoning using the Boeing 10-K dataset.
import json, fastmemory

m = fastmemory.SearchMemory([("Travel over $500 must be approved by a manager.", "policy.md"),
                             ("Expense reports are due within 30 days.", "policy.md")])
r = json.loads(m.search("manger aproved", 5))
# r["stage"] == "fuzzy"; r["corrections"] == [["manger", "manager", 0.44], ["aproved", "approved", 0.67]]
# r["hits"][0]["text"] starts "Travel over $500 must be approved by a manager."
The fuzzy stage runs only when no word matches exactly or by stem. Very short or heavily misspelled words (e.g.
"trvel") may not be corrected; then the result says so (matched: false, handoff: true) instead of guessing.
Plain prose is split into passages, and ## [ID: x] ATF sections are detected. Each search reports how it matched
(stage: exact, substring, stem, fuzzy, hub, or empty for an empty memory, plus any spelling corrections), its term_coverage and confidence, and
a handoff flag, so an agent can tell a confident match from a guess. In Rust: search::Memory::from_documents
and Memory::search.
-
Clustering: FastMemory clusters with its optional native clustering engine when its compiled library is available, and otherwise with the built-in Louvain.
-
the native engine is loaded at run time from the first of these locations:
FASTMEMORY_NATIVE_LIB, which must be an absolute path;- the directory of the library that contains FastMemory, where packages bundle it;
- the directory of the executable.
It is never loaded from the working directory or the system library search path.
-
louvain_backend::status()reports which backend is in use, and why when it is the fallback. -
FASTMEMORY_CLUSTER=builtinforces the built-in Louvain. -
Settings:
FASTMEMORY_NATIVE_RESOLUTION(default 1.0) andFASTMEMORY_NATIVE_MAX_LEVELS(default 0, which means unlimited). -
Both backends give the same blocks for the same input in every run.
-
-
Embedding the library: use the core without the CLI, server and license telemetry:
fastmemory = { version = "0.4", default-features = false }
That leaves the parser,
cluster::partition/cluster::run_louvainand the backend loader. It has no network code and no async runtime. The default features keep the CLI and the server. -
Telemetry is opt-in. FastMemory sends nothing unless a license key is configured (
FASTMEMORY_LICENSE_KEY, for license verification) or you setFASTMEMORY_TELEMETRY=1. When enabled, the ping toapi.fastbuilder.aiincludes the host name, CPU vendor and public IP.
FastMemory is designed to integrate into complex, high-throughput data ecosystems. While it natively clusters Markdown-based Atomic Text Functions (ATFs) via Louvain, in production environments where data is distributed across Data Warehouses, Data Lakes, and specialized analytics platforms, FastMemory acts as an ontological orchestrator and agentic query engine bridging structured pipelines and autonomous AI logic.
For detailed integration patterns with Snowflake, BigQuery, Databricks, AWS Glue, Microsoft Fabric, and Neo4J, see the Architecture Guide.
| Standard RAG Robot Brain | FastMemory Topology Robot Brain |
|---|---|
 |
 |
- Agentic Apps & SaaS: Integrate
fastmemory mcpdirectly into your proprietary AI loops. Instead of sending agents to vector DBs, send them into a FastMemory graph where they can extract isolated, functional context blocks to execute workflows. - Fast Software Engineering: In FastBuilder.AI, FastMemory acts as the structural brain for rapid feature development. By indexing the entire application architecture into an ontological graph, coding agents can query precisely how a proposed change will impact distant, decoupled components.
- The Possibilities are Endless: Medical diagnostics routing, autonomous drone navigation logic, compliance auditing, etc.
FastMemory is and will always be free and open-source under the MIT License.
For teams and organizations that need managed deployments, compliance tooling, security monitoring, and dedicated support, we offer FastStudio — a packaged platform built on top of FastMemory that provides:
- 🔒 Compliance & Governance (BuildRight) — automated ontological compliance rules
- 🛡️ Security Monitoring (SafeSemantics) — real-time semantic threat detection
- 📊 Data Memory Management — topology visualization, audit trails, and RBAC
- 🤝 Dedicated Support — SLA-backed assistance from the FastMemory core team
Note
You do not need FastStudio to use FastMemory. Every feature in this repository is fully functional and unrestricted. FastStudio is for teams that want a managed, production-hardened experience with compliance and security baked in.
👉 Learn more about FastStudio →
This project is licensed under the MIT License — free for personal, commercial, and organizational use without restriction.
We welcome contributions! Whether it's bug fixes, new integration patterns, additional domain examples, or performance improvements — open a PR or start a discussion.
Built with 🛡️💻🧠 by FastBuilder.AI