

An operating system for LLM inference: generate the compute for your hardware, page models larger than memory, and move execution without losing the conversation.
jitllm.org · Documentation · Source · Latest release
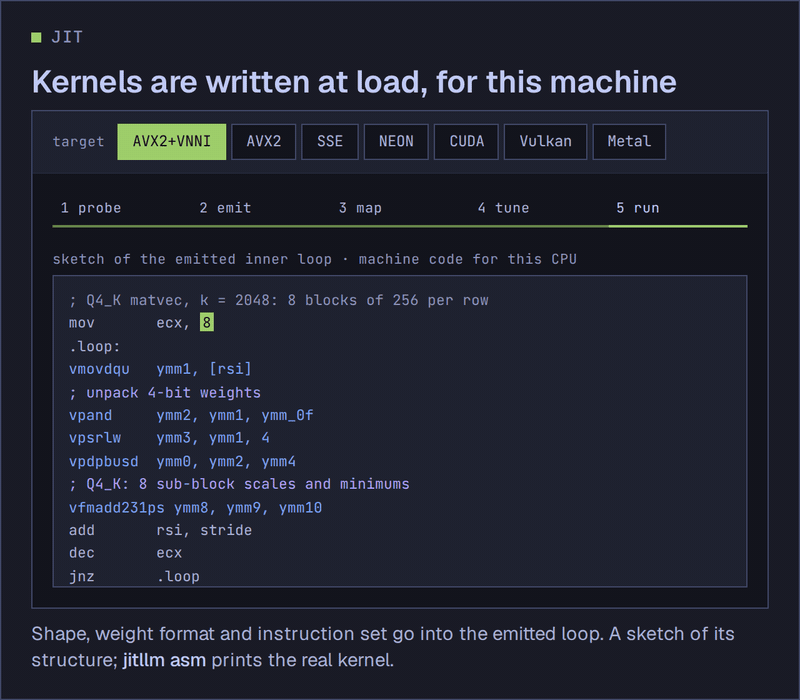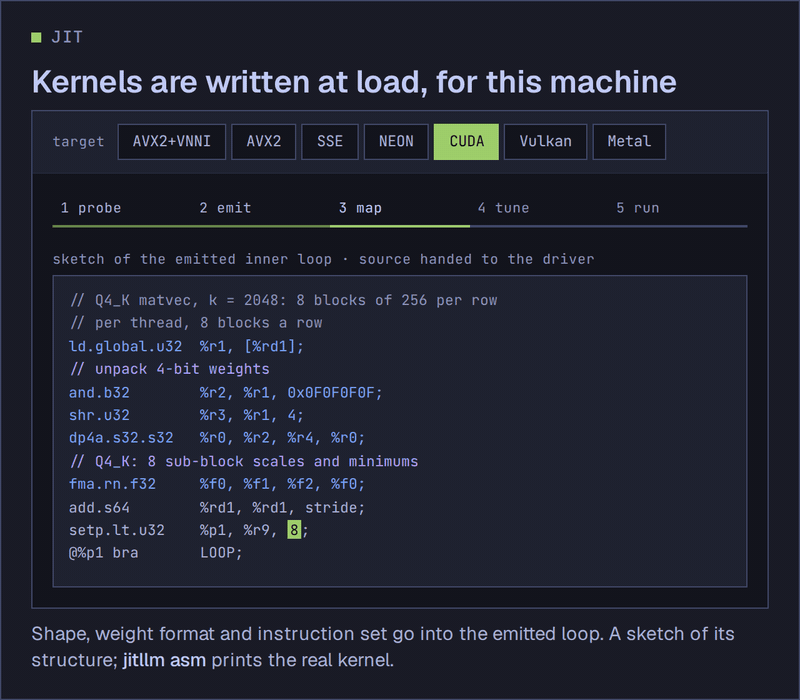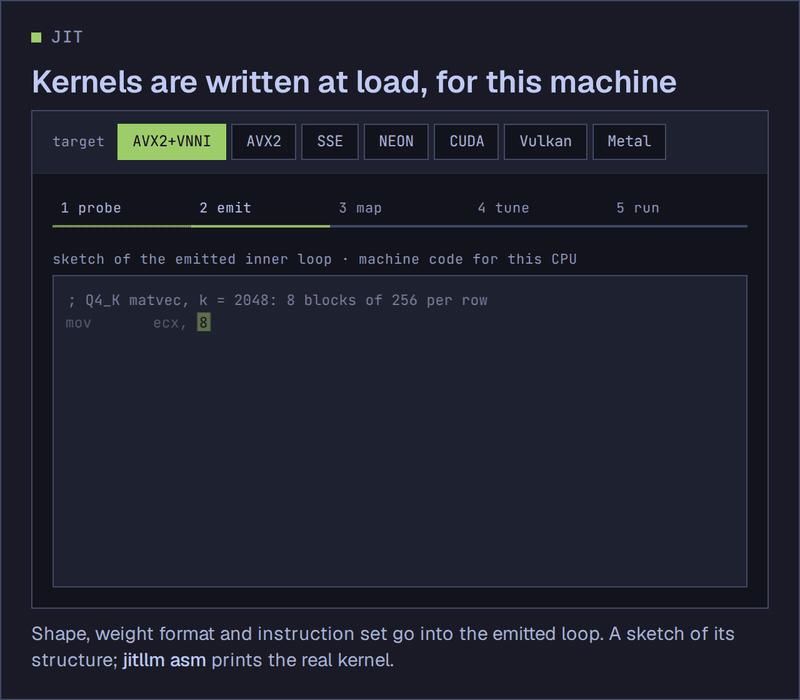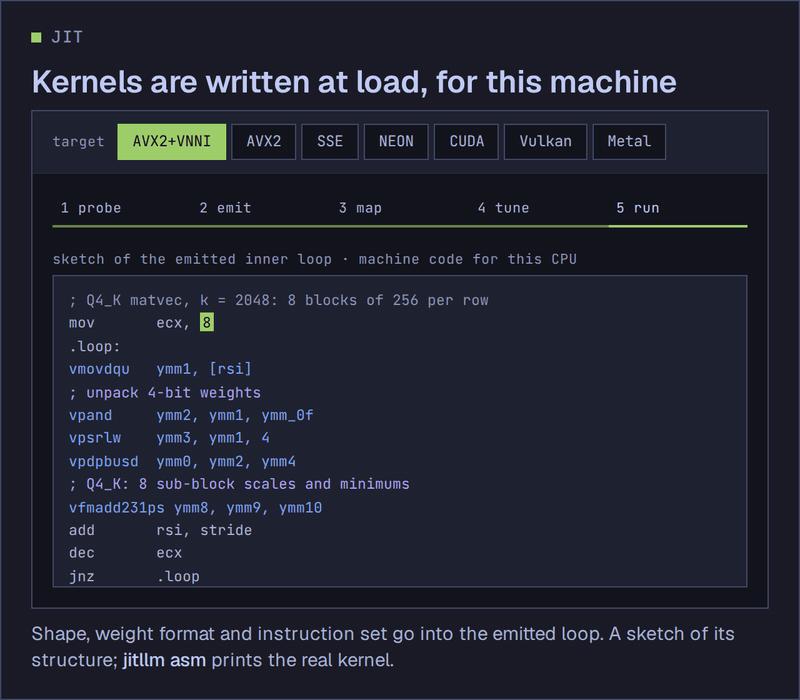
- Every kernel JIT-generated at load time for your CPU (AVX2, SSE, NEON) or GPU (CUDA, Vulkan, Metal), specialised to the model's shapes and weight formats. No precompiled kernels or interpreted compute fallback.
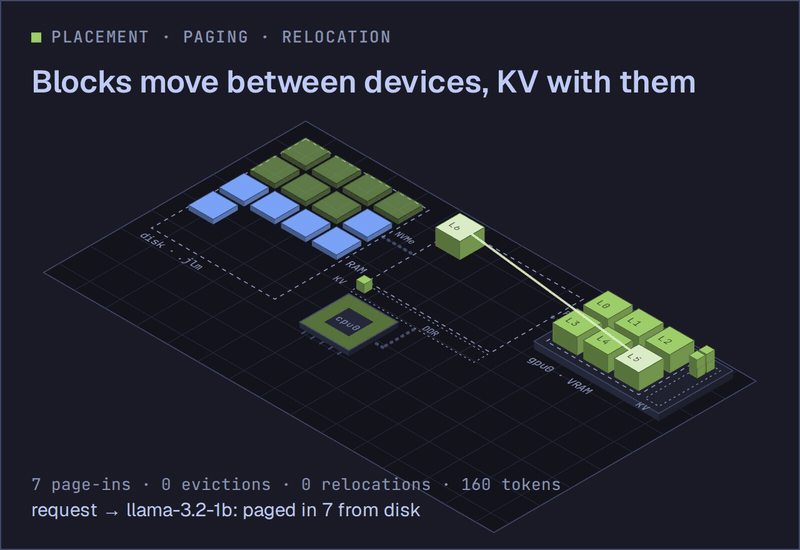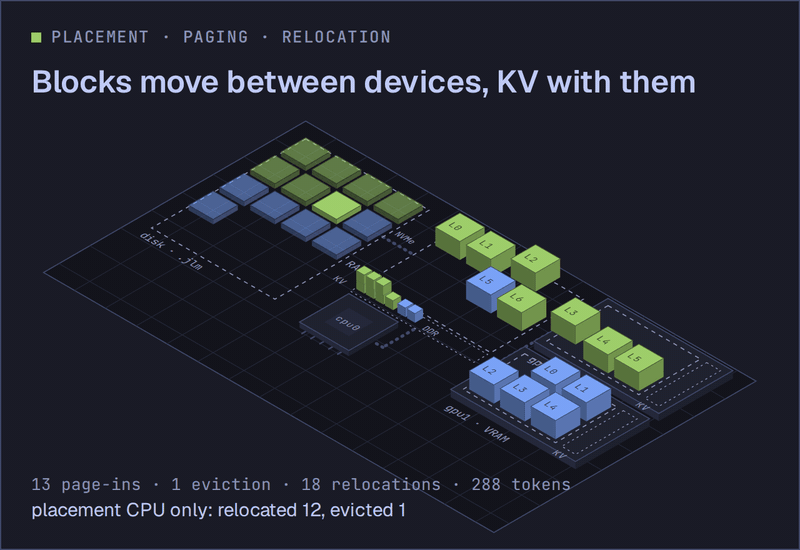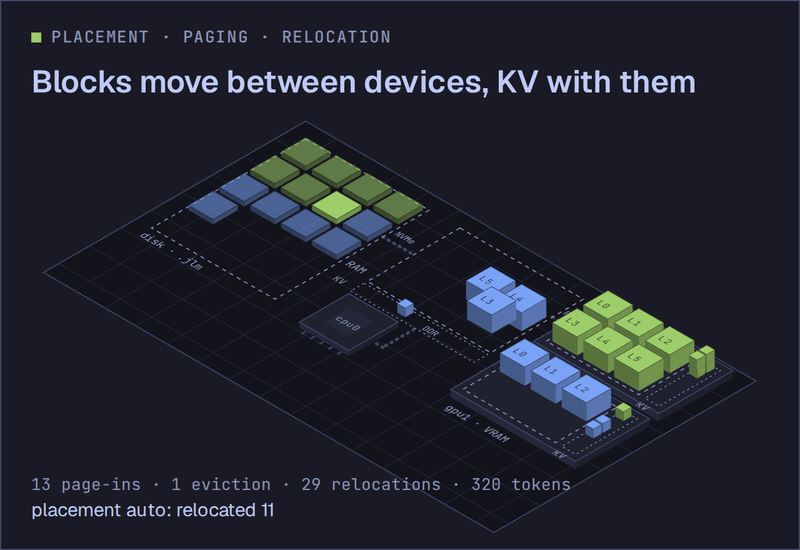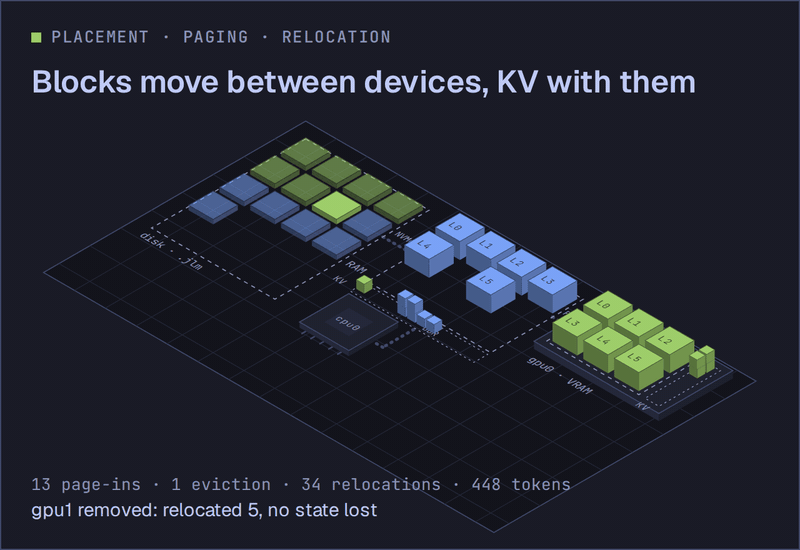
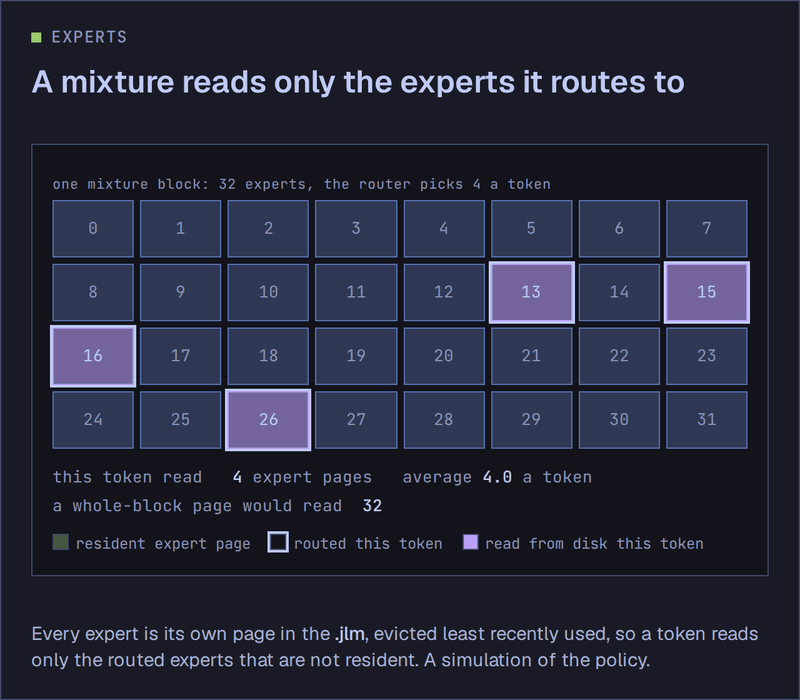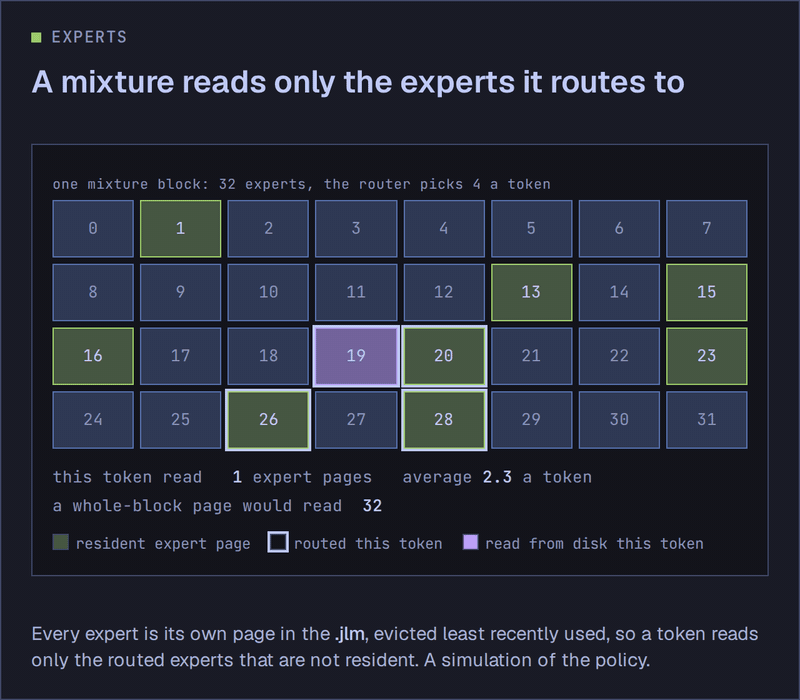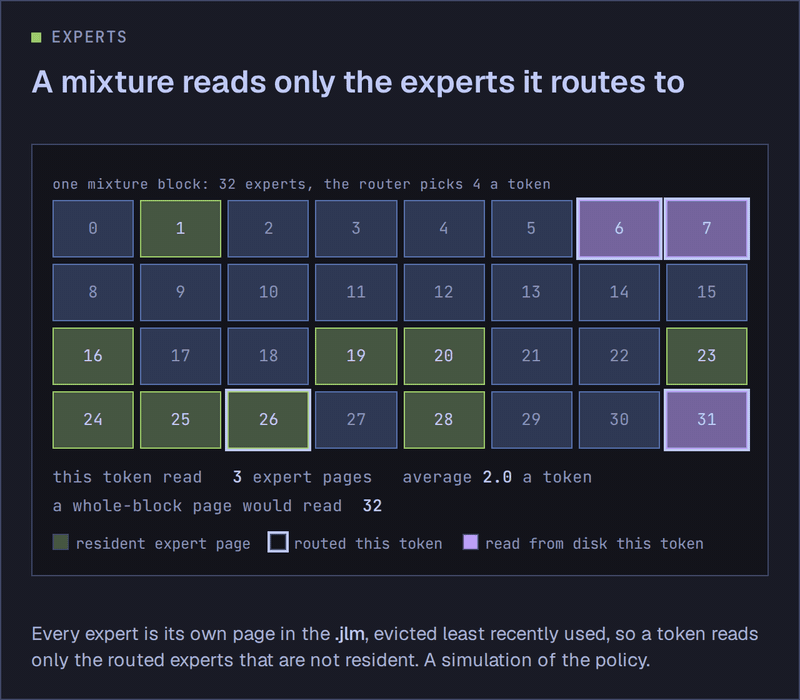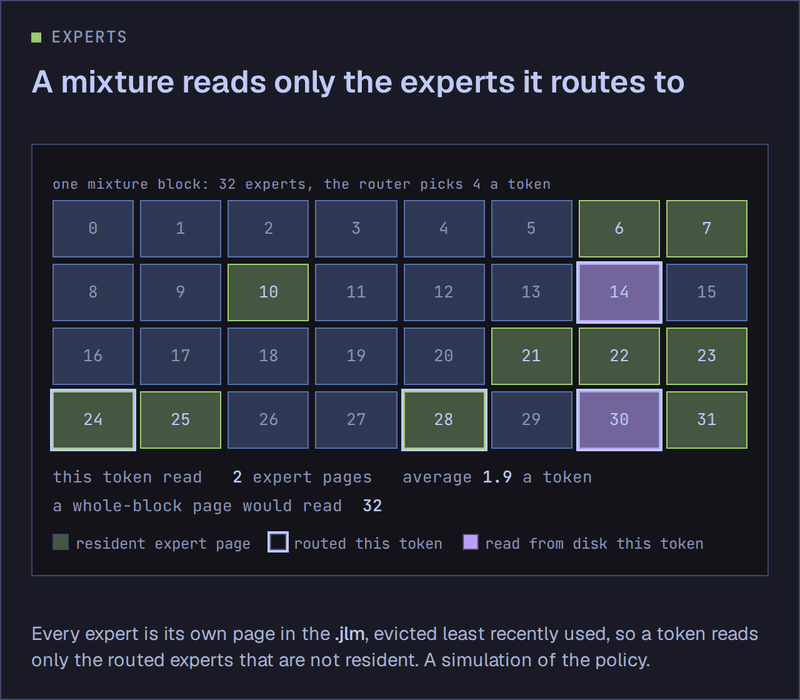
- Disk, RAM and VRAM form the memory system. Weights, routed MoE experts and KV state page as needed. Blocks move between CPU and GPUs at run time, carrying their attention and recurrent state with them.
- Runs everywhere, depends on nothing. One binary per platform (Linux, macOS, Windows; x86 and Arm) that finds CUDA, Vulkan or Metal at run time and otherwise runs on the CPU.
Serve it as an OpenAI- and Anthropic-compatible API with streaming and tool calling from one standalone binary, jitllmd, or embed it as a Go library. There are desktop and terminal apps too.
Linux and macOS:
curl -fsSL https://jitllm.org/install.sh | shWindows (PowerShell):
irm https://jitllm.org/install.ps1 | iex